


[May-2026] SPS-C01 Exam Dumps - Free Demo & 365 Day Updates
Free Sales Ending Soon - Use Real SPS-C01 PDF Questions
NEW QUESTION # 170
A data engineering team is developing a Snowpark stored procedure in Python to perform anomaly detection on time-series data stored in a Snowflake table named 'sensor_readingS. The stored procedure needs to efficiently process large volumes of data and return only the rows identified as anomalies. Which of the following approaches would provide the most performant and scalable solution for operationalizing this stored procedure?
- A. Use the method to include a pre-trained anomaly detection model (pickled object) in the stored procedure's execution environment. Load the model, use it to predict on the data fetched using 'session.table(Y , and return a Snowpark DataFrame of anomalies.
- B. Use the Snowpark API to directly perform anomaly detection calculations (e.g., rolling statistics, z-score calculations) on the 'sensor_readings' table within the stored procedure, leveraging Snowpark's distributed processing capabilities, and then return the resulting Snowpark DataFrame containing only the anomalies.
- C. Create a UDF with a Scala implementation and use it inside the Snowpark stored procedure to detect anomalies using the Scala implementation for increased processing power.
- D. Execute a SQL query from within the stored procedure using the Snowflake connector for Python to fetch the relevant data, then use a standard Python loop to iterate through the results and apply anomaly detection logic. Return the anomalous rows as a list of dictionaries.
- E. Load the entire 'sensor_readings' table into a Pandas DataFrame within the stored procedure, perform anomaly detection using a Python library like 'scikit-learn' , and then create a Snowpark DataFrame from the filtered Pandas DataFrame to return the results.
Answer: B
Explanation:
Option B is the most performant and scalable. It leverages Snowpark's distributed processing to perform the anomaly detection calculations directly on the Snowflake data, avoiding the overhead of transferring large datasets to Pandas DataFrames or using inefficient Python loops. Using a SQL Query inside the stored procedure would work but not as efficient as Snowpark dataframes that are lazy executed. Transferring data into a pandas dataframe is also inefficient as it reduces Snowflake's ability to perform the computation inside Snowflake's distributed framework. Lastly a Scala UDF would still require data transfer between Snowpark and Scala, which makes it ineffecient.
NEW QUESTION # 171
You are developing a Snowpark Python application to process large datasets stored in a Snowflake table called 'CUSTOMER DATA' The application needs to perform complex data transformations and aggregations that benefit from Snowpark's lazy evaluation and query optimization. Which of the following approaches will lead to the MOST efficient execution in terms of resource utilization and performance?
- A. Load the data into a temporary table, then create a Stored Procedure in SQL to perform transformations, and call the procedure from the Snowpark Python application.
- B. Execute a series of individual SQL queries using 'session.sql()' to perform the transformations and aggregations, and then combine the results into a final Pandas DataFrame for further processing before loading it back into Snowflake.
- C. Fetch all the data from 'CUSTOMER_DATR into a Pandas DataFrame using , perform the transformations in Pandas, and then load the results back into a new Snowflake table using 'session.write_pandas()'.
- D. Use 'session.table('CUSTOMER to fetch all the data into a list of Row objects in Python, perform transformations using standard Python loops and data structures, and then write the processed data to a new Snowflake table using 'session.createDataFrame(V.
- E. Create a Snowpark DataFrame from the "CUSTOMER_DATX table using 'session.table('CUSTOMER DATA')', perform all the transformations and aggregations using Snowpark DataFrame API, and materialize the final result into a new Snowflake table using .
Answer: E
Explanation:
Option B is the most efficient. Snowpark's lazy evaluation and query optimization allow Snowflake to execute the entire transformation pipeline within the data warehouse, minimizing data transfer and leveraging Snowflake's compute resources. Fetching all data to Pandas (A and D) moves computation out of Snowflake. Executing individual SQL queries (C) loses Snowpark's optimization benefits. SQL stored procedure (E) might be more efficient than some options, but Snowpark provides a better integrated solution.
NEW QUESTION # 172
You have a Snowpark Python UDF that performs sentiment analysis on customer reviews. The UDF relies on a pre-trained machine learning model stored as a file in a Snowflake stage. To enhance security, you want to create a secure UDF. Which of the following steps are necessary to achieve this?
- A. Wrap the UDF creation in a stored procedure with 'EXECUTE AS CALLER to elevate privileges and ensure model access.
- B. When creating the UDF, specify 'secure=True' in the 'CREATE FUNCTION' statement, and explicitly grant USAGE privilege on the stage containing the model file to the role that executes the UDF using 'GRANT USAGE ON STAGE TO ROLE
- C. Grant USAGE privilege on the stage containing the model file to the SNOWFLAKE.DATA_GOVERNANCE role.
- D. Grant READ privilege on the stage containing the model file to the role that owns the secure UDF.
- E. Ensure the function definition specifies a 'context' parameter to pass security context.
Answer: B,D
Explanation:
Secure UDFs require explicit grants to access resources. Granting READ privilege on the stage to the UDF owner ensures access during definition. 'secure=True' makes the UDF secure. 'USAGE ON STAGE must be granted to the role executing the UDF to allow it to read from the stage at runtime. 'SNOWFLAKE.DATA GOVERNANCE' role doesn't automatically grant access, and 'EXECUTE AS CALLER is not directly related to granting access to the model file. 'context' is not a standard parameter for UDF definitions and does not manage security context directly.
NEW QUESTION # 173
You have a Snowpark Python UDTF named that performs complex data transformations and you want to share it securely with another Snowflake account. Select ALL the necessary steps and considerations to properly share this UDTF using Snowflake Secure Data Sharing.
- A. Ensure the UDTF doesn't rely on any external packages or dependencies not available in the target account.
- B. Grant OWNERSHIP privilege on the UDTF to the share.
- C. Create a share and grant usage on the database containing the 'process_data' UDTF to the share.
- D. Create a secure UDTF and add it to share.
- E. Grant SELECT privilege on the UDTF to the share.
Answer: A,C,D,E
Explanation:
To share a UDTF, you first create a share and grant USAGE on the database containing it (A). Then, you create the UDTF as SECURE to ensure data is protected (B). SELECT is needed to allow the share to actually use the function (C). It is important to make sure that the receiving account will be able to run the UDTF, so ensure all of the needed packages and dependendies are accounted for (D). GRANT OWNERSHIP would mean you would not be able to make changes to the function (E).
NEW QUESTION # 174
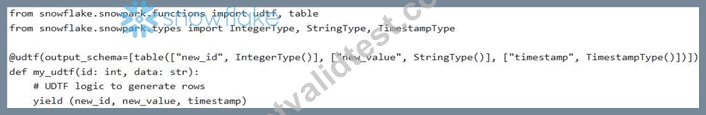
You have a Python function that performs complex data transformations, too intricate to express directly in Snowpark SQL. You want to register this as a User-Defined Table Function (UDTF) so that it can be used to expand rows in a Snowpark DataFrame. The UDTF takes two arguments: an ID (integer) and a string. It returns a table with three columns: (integer), (string), and 'timestamp' (timestamp). Which of the following code snippets correctly registers this UDTF, making it available for use within Snowpark?
- A.
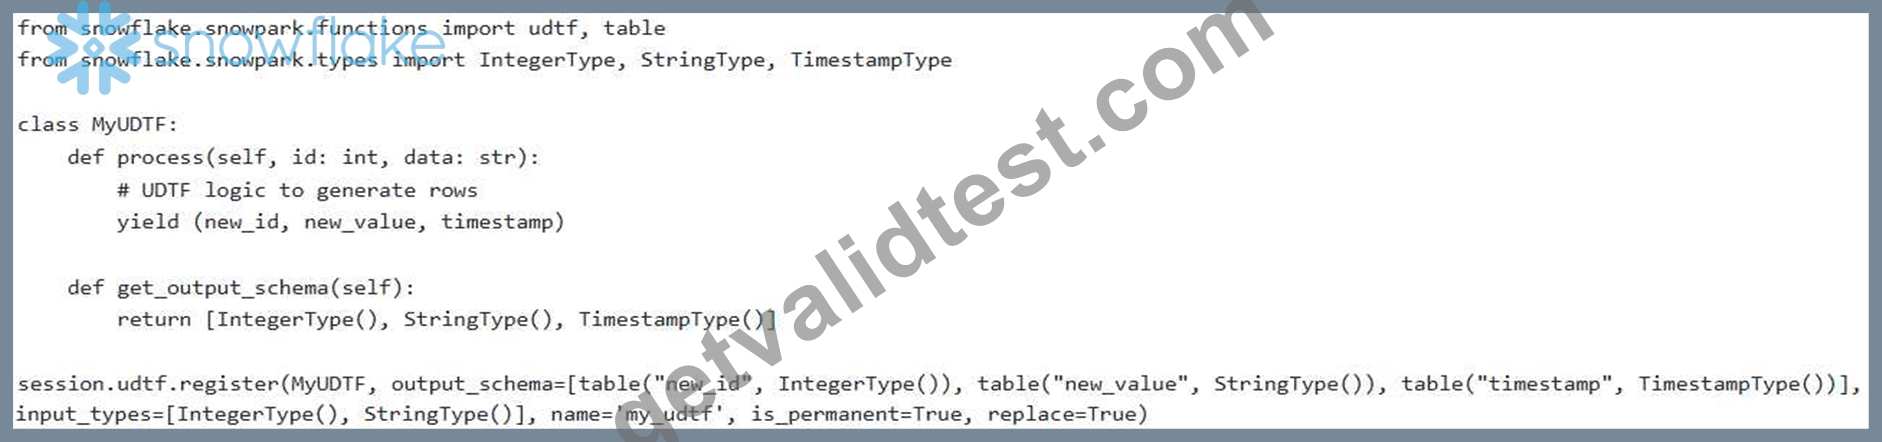
- B.
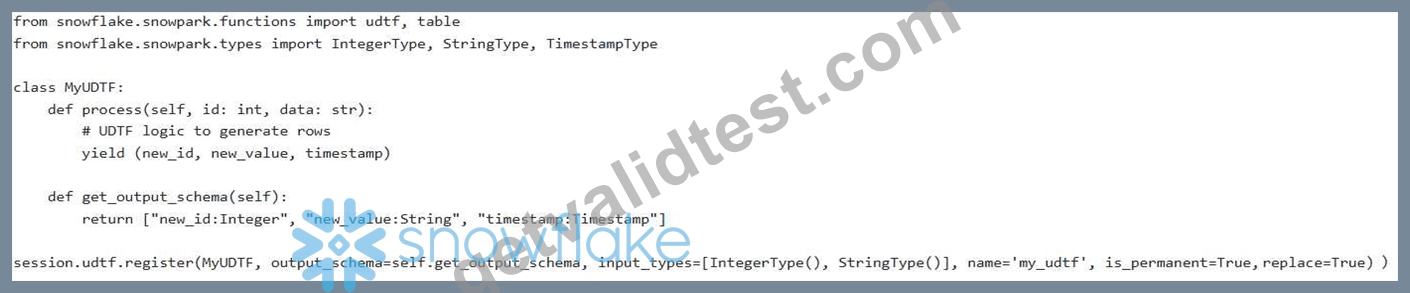
- C.
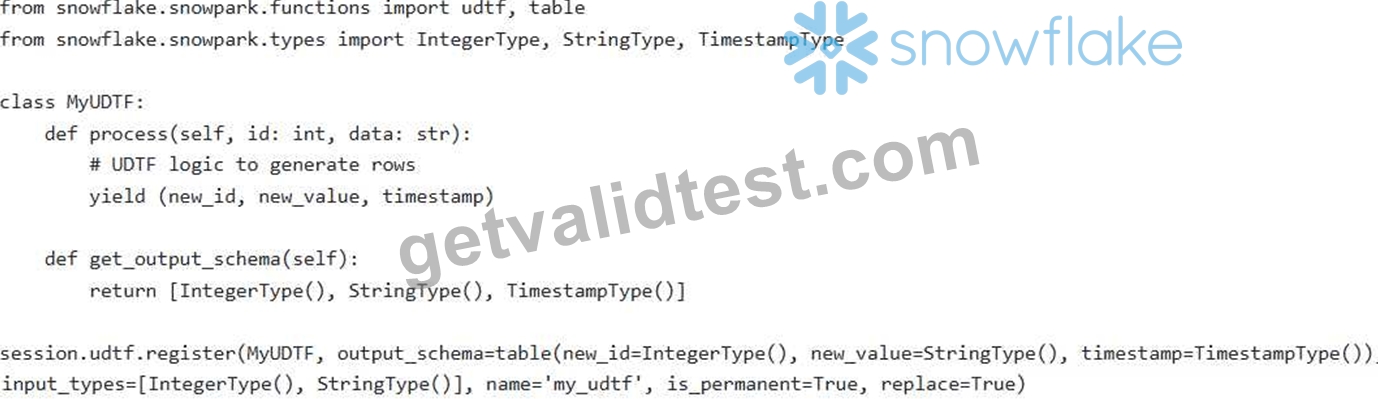
- D.
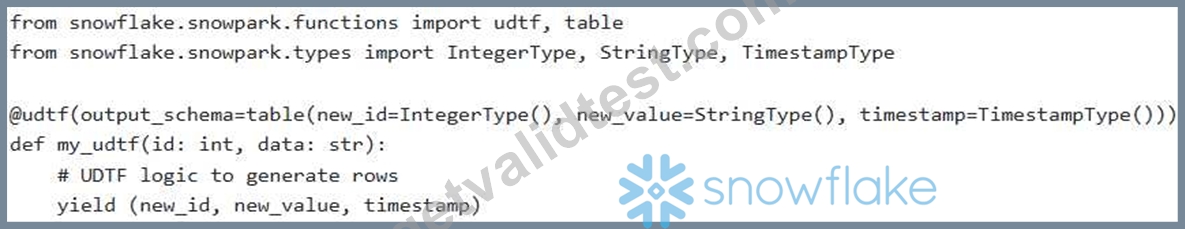
- E.
Answer: C
Explanation:
Option C provides the correct way to define and register UDTFs using the class-based approach in Snowpark. It defines the UDTF class with 'process' and methods. returns the schema using 'table' function correctly. Options A and B use the decorator approach, which is valid for simple UDTFs, but it's less flexible than the class-based approach, especially for managing complex state or schema. Option D uses the class-based approach but incorrectly defines the 'output_schema' when registering. Option E has an incorrect definition of return type.
NEW QUESTION # 175
You are developing a Snowpark application that requires calling a stored procedure. Which of the following approaches is the MOST secure and efficient way to call a stored procedure from your Snowpark Python code, assuming the stored procedure returns a single value?
- A.

- B.

- C.

- D.

- E.

Answer: E
Explanation:
The 'session.call()' method (B) is the most direct and efficient way to call a stored procedure and retrieve its single return value from Snowpark Python. It handles the execution and data retrieval efficiently. Using 'session.sql()' (A and C) is less efficient as it requires parsing SQL and manual extraction of the result. 'session.sproc()' (D) is generally used to register Python functions as stored procedures and not for calling existing ones. is not valid, 'session.call()' is the right way to call procedure
NEW QUESTION # 176
You have a Python function, 'calculate metrics(df: snowpark.DataFrame, metric name: str) -> snowpark.DataFrame', that calculates various metrics on a Snowpark DataFrame. You want to deploy this function as a stored procedure in Snowflake. You need to ensure that the stored procedure has appropriate permissions to read data from a table named 'customer data' and write results to a table named 'metrics_table'. Which of the following steps are necessary to achieve this, assuming you are using the 'session.sproc.register' method?
- A. Specify the 'packages' argument in 'session.sproc.register' to include any Python dependencies required by the 'calculate_metrics' function.
- B. Grant the 'SELECT privilege on the 'customer_data' table and the 'INSERT privilege on the 'metrics_table' table to the role executing the stored procedure.
- C. Grant the 'USAGE privilege on the database and schema containing the 'customer_data' and 'metrics_table' tables to the role executing the stored procedure.
- D. Specify the 'imports' argument in 'session.sproc.register' with the list of packages which are needed to run 'calculate_metrics' function.
- E. When registering the stored procedure using 'session.sproc.register' , specify the argument and provide a 'replace=True' if necessary. This will allow you to assign ownership of the stored procedure to a role with the necessary privileges.
Answer: A,B,E
Explanation:
Options B, C, and D are correct. B is required to give the stored procedure permissions to read and write data to the appropriate tables. C: Making the SP permanent allows you to grant ownership to a specific role. D: The packages argument is essential for including any external Python dependencies needed by the function. Option A provides access to the database and schemas but does not grant access to the tables themselves. Option E provides a way to pass files that need to be used inside the function.
NEW QUESTION # 177
You have a Snowpark DataFrame 'sales df with columns 'product_id' (INTEGER), 'sale date' (DATE), and 'sale_amount' (DOUBLE). You need to filter the DataFrame to include only sales that occurred in the year 2023 and where the 'sale_amount' is greater than the average 'sale_amount' for that specific 'product id'. Which of the following Snowpark Python code snippets will correctly achieve this?
- A.

- B.

- C.

- D.

- E.

Answer: B
Explanation:
Option C is the most efficient and correct. It calculates the average sale amount per product ID using a window function and then filters the DataFrame based on both the year and the comparison with the average. It avoids joins and 'collect()' which can be inefficient. Option A doesn't import Window or properly use avg over a window, causing an error. Option B requires a join, which is less efficient. Option D uses "mean' which is available but 'avg' is preferrable. Option E 'collects data to the client which is also generally avoided in Snowpark.
NEW QUESTION # 178
You have two Snowflake tables, 'customers' and 'orders'. The 'customers' table contains customer information, including a 'customer id' and 'region'. The 'orders' table contains order information, including 'order id', 'customer id', and 'order amount'. You need to create a Snowpark DataFrame that joins these two tables on 'customer id' and calculates the total order amount per region. However, some customers may not have any orders, and you want to include all customers in the result, with a total order amount of 0 for those without orders. Which of the following Snowpark code snippets will achieve this goal MOST efficiently, assuming 'customers_df and 'orders_ff are pre-existing Snowpark DataFrames representing the respective tables?
- A.

- B.

- C.

- D.

- E.

Answer: A
Explanation:
Option B is the most efficient because it uses 'coalesce' directly within the 'agg' function, avoiding a separate .na.fill' operation which could be less optimized in Snowpark. It handles the null values resulting from the left outer join correctly, ensuring that customers without orders have a 0 total order amount. Options A and C might work in some contexts, but are less idiomatic and potentially less efficient. Options D and E are less concise and may not be the most optimal way to express the desired logic in Snowpark.
NEW QUESTION # 179
You are working with a Snowpark DataFrame named containing information about products, including 'CATEGORY , 'SUBCATEGORY , and 'PRICE'. You want to determine the maximum price for each subcategory within each category. Furthermore, you need to filter the results to only include categories that have more than 5 subcategories. Which of the following Snowpark Python code snippets accomplishes this task? (Select all that apply)
- A.

- B.

- C.
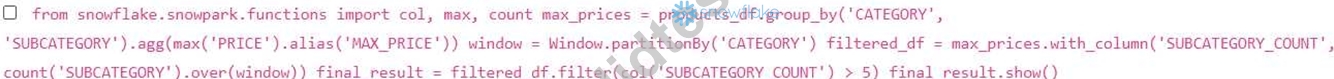
- D.

- E.

Answer: B,E
Explanation:
The correct options are D and E. They both address the requirement and count distinct subcategories within each category. Option D: Correctly calculates the maximum price for each subcategory within each category. Then separately calculates the count of DISTINCT subcategories for each category. Filters the categories to include only those with more than 5 subcategories. Joins the two resulting DataFrames to provide the final output. This is a standard and explicit way to accomplish the task. Using countDistinct to ensure each subcategory is only counted once. Option E: Aggregates Max Price and CountDistinct of subcategory into same dataframe, this addresses all requirements in a more concise manner. Option A: Does not give the right result since 'count' will not give the countDistinct. Also using 'COUNT(SUBCATEGORYV in category_countS dataframe results in count of all rows in the group instead of the number of groups (number of Subcategories). Option B: Window functions is irrelevant here, and requires more coding while can be handled efficiently by aggregating and countDistinct combination Option C: Option C doesn't aggregate maximum price for each subcategory within each category as the question mentions.
NEW QUESTION # 180
You are tasked with creating a Snowpark UDTF (User-Defined Table Function) in Python to process a large CSV file stored in a Snowflake stage. Each row in the CSV represents a transaction, and you need to parse each row and extract specific fields based on a complex set of rules. The UDTF should return a table with the extracted fields. Consider the following code snippet:
- A. The UDTF will fail because the 'yield' statement is being called after using 'return' in the processing block. Remove the yield statement as it is incompatible.
- B. The UDTF will execute correctly and efficiently in Snowpark, correctly processing each row of the CSV and returning the extracted fields as a table.
- C. The code will raise an error because the 'read_csvs function is not available within the Snowpark UDTF context. The input needs to be processed differently.
- D. The UDTF will run, but it will be slow due to the use of pandas DataFrame operations within the UDTF. Consider optimizing the code to use Snowpark DataFrame operations instead.
- E. The UDTF will run but will not return any data since the code currently lacks a 'session' object properly initialized for Snowpark operations inside the handler. Ensure the handler method has the session parameter and uses it.
Answer: D
Explanation:
While the provided code snippet might function, it's fundamentally inefficient. UDTFs in Snowpark are most performant when leveraging Snowpark DataFrame operations. Using 'pandas' inside the UDTF serializes and deserializes data between the Snowflake engine and the Python environment, introducing significant overhead. Options B, D and E are all generally incorrect as the code snippet provided is syntactically okay and contains the session parameter. A is incorrect due to performance and lack of optimization.
NEW QUESTION # 181
You are working with a Snowpark DataFrame containing website traffic data'. The DataFrame has columns like 'date' , 'page_url', and 'visit_count'. You need to calculate the cumulative sum of visit counts for each 'page_url' over time (i.e., ordered by 'date'). However, you only want to consider data from the last 30 days for each calculation. Which of the following Snowpark code snippets will correctly achieve this using window functions with a frame specification?
- A.

- B.

- C.

- D.

- E.

Answer: A
Explanation:
Option B is correct because it uses 'rangeBetween(-30, 0)' which specifies a frame that includes all rows within a range of 30 days preceding the current row, based on the ordering defined by the "date" column. Since 'date' column is used for ordering, we need to use rangeBetween' and NOT 'rowsBetween' . Also, we need to use 'sf.sum()' for Snowflake functions'. If the column is of Timestamp type, 'rangeBetween' represents days only, and in case it's numeric type represents numeric interval. Option A calculates the cumulative sum from the beginning of time for each page URL. Option C doesn't correctly specify the end of the frame. Option D has incorrect syntax and may not work. Option E uses incorrect sum function as well, as it misses sf prefix.
NEW QUESTION # 182
A Snowpark Python application is experiencing significant performance degradation when processing a large dataset (100GB+) stored in Snowflake. The application performs a complex series of transformations, including window functions and joins with smaller lookup tables. You suspect data skew is contributing to the issue. Which of the following strategies would be MOST effective in mitigating the impact of data skew and improving performance?
- A. Increase the warehouse size to a larger instance (e.g., from X-Small to Large).
- B. Implement salting or pre-partitioning of the data based on a hash of the skewed column before performing the joins and window functions.
- C. Convert the Snowpark DataFrame to a Pandas DataFrame before performing transformations.
- D. Disable query result caching to ensure fresh data is always used.
- E. Cache the smaller lookup tables using 'session.createDataFrame' and broadcast them to all worker nodes.
Answer: B
Explanation:
Salting or pre-partitioning addresses data skew directly by distributing the skewed values more evenly across partitions. Increasing warehouse size (A) might help to some extent but doesn't solve the underlying skew issue. Broadcasting small tables (C) is a good optimization, but it's less effective if the larger dataset is skewed. Disabling query result caching (D) is irrelevant to data skew. Converting to Pandas (E) will likely make performance worse for large datasets due to data transfer overhead and limitations of single-node processing.
NEW QUESTION # 183
You are working with a Snowpark DataFrame containing employee data, including columns 'employee_id', 'first_name', 'last_name', 'salary', and 'department'. You need to perform the following transformations: 1. Concatenate 'first_name' and into a new column called separating them with a space. 2. Increase each employee's salary by a percentage based on their 'department'. Department 'Sales' gets a 10% raise, 'Marketing' gets a 15% raise, and all other departments get a 5% raise. 3. Create a new column reflecting this raise. Which of the following Snowpark code snippets achieves these transformations correctly and efficiently? (Select all that apply)
- A.

- B.

- C.

- D.

- E.

Answer: A,C
Explanation:
Options A and C are correct. Option A uses 'concat for string concatenation and 'when' for conditional salary calculation, which is a standard and efficient approach in Snowpark. Option C uses a Snowflake expression to achieve the same conditional salary calculation, which can be more concise for complex conditions and may leverage Snowflake's optimization. Option B is incorrect, because the '+' string concatenation will not work; string concatenation in Snowpark should happen using the 'concat' function. Option D is less efficient because it uses a Python UDF, which involves serialization/deserialization overhead. Option E will not work because of syntax 'select(' 'Y does not exist, therefore the user will need to specify all the columns. Also, there is a column called ' ' which will break the processing.
NEW QUESTION # 184
You are tasked with optimizing a Snowpark Python application that performs complex geospatial calculations on a large dataset. The application experiences significant performance bottlenecks due to the computational intensity of the geospatial functions. Which of the following strategies would be MOST effective in improving performance?
- A. Increase the size of the virtual warehouse to a larger instance (e.g., from X-SMALL to LARGE).
- B. Rewrite the geospatial functions using native Python libraries within the Snowpark environment.
- C. Utilize user-defined functions (UDFs) written in Java or Scala and leverage vectorized UDFs where possible.
- D. Distribute the dataset into smaller chunks using partitioning strategies within the Snowpark DataFrame API and process them independently.
- E. Disable automatic query optimization features in Snowflake to gain more control over query execution.
Answer: C
Explanation:
Vectorized UDFs written in Java or Scala offer significant performance gains compared to Python UDFs due to their lower overhead and ability to leverage JVM optimizations. Increasing the warehouse size (A) might help, but it's not the most targeted solution for computationally intensive tasks. Partitioning (C) can help with data distribution, but the bottleneck remains the calculation itself. Native Python libraries (D) might not be as performant as optimized JVM-based UDFs. Disabling query optimization (E) is generally not recommended and can negatively impact performance.
NEW QUESTION # 185
You are tasked with creating a Snowpark DataFrame from a series of large Parquet files stored in an external stage 'my_stage' . The files contain customer transaction data, but some files are corrupted and cause errors during DataFrame creation. You want to implement a solution that skips the corrupted files and logs the filenames of those files to a table named 'failed_files'. Assuming you have a Snowpark session 'session' and a UDF that inserts filenames into the 'failed_files' table, which of the following approaches is the MOST efficient and robust way to achieve this, while minimizing impact on performance and maintaining data integrity? Consider that you don't have direct control over the file format and data quality within the stage.
- A. Use 'session.read.parquet('stage://my_stage/ within a try-except block to catch errors. Inside the 'except' block, call with the filename. Retry the read operation for remaining files after removing the failing file from stage.
- B. Implement a custom file listing function using 'session.sql('LlST to identify potentially corrupted files by checking file size or metadata, then exclude these files when creating the Snowpark DataFrame. Use 'session.read.parquet' with the filtered list of files.
- C. Create a Snowpark DataFrame using 'session.read.option('mode', 'PERMISSIVE').parquet('stage://my_stage/ ')'. This automatically skips corrupted records within valid files but doesn't handle entire corrupted files. Afterward, compare the counts of each file before and after processing to identify corrupted files based on lost records.
- D. Use the command in Snowflake to load the Parquet files into a temporary table, specifying the 'ON ERROR = CONTINUE option. Then, create a Snowpark DataFrame from the temporary table. Log any rejected files using a 'VALIDATION MODE = RETURN ERRORS' copy command before creating the temporary table.
Answer: D
Explanation:
Option C is the most efficient and robust. 'COPY INTO with = CONTINUE directly leverages Snowflake's optimized loading capabilities to handle file-level errors gracefully. The 'VALIDATION_MODE allows identifying errored files before the load process. A, B, D and E involve more complex and potentially less efficient workarounds within Snowpark itself.
NEW QUESTION # 186
You are developing a Snowpark Python application that needs to process large datasets. You want to optimize performance by leveraging user-defined functions (UDFs) to perform complex calculations in parallel across the Snowflake data warehouse. Which of the following statements regarding Snowpark UDFs are TRUE?
- A. To ensure optimal performance, it is recommended to always use the default Snowflake Anaconda channel for UDF dependencies, as custom channels may introduce latency.
- B. Snowpark Python UDFs are always executed in a single process on the Snowflake warehouse, limiting their parallel processing capabilities.
- C. Snowpark UDFs automatically distribute the data and computation across multiple nodes in the Snowflake warehouse, but the distribution strategy cannot be controlled by the developer.
- D. Snowpark UDFs can be defined using either Python or Java, providing flexibility in choosing the programming language best suited for the task. The Java UDF creation method will allow faster execution speeds.
- E. Snowpark UDFs can be defined as either scalar UDFs (processing one row at a time) or vectorized UDFs (processing batches of rows), offering different performance characteristics.
Answer: C,E
Explanation:
Snowpark UDFs can be either scalar or vectorized, offering different performance tradeoffs. Vectorized UDFs are generally more efficient for large datasets as they process batches of rows. Snowpark UDFs do distribute the data and computation across multiple nodes automatically; however, the distribution strategy, while not directly controlled, is influenced by how the UDF is applied to the data and the inherent distribution of the underlying data itself. Python is the primary UDF language. Option A is false because UDFs are designed for parallel processing. Option C is not always true; custom channels might be necessary for specific dependencies. Option E is partially correct in the older releases but Python is used primarily now.
NEW QUESTION # 187
You have a Snowflake table named 'RAW EVENTS with a large number of events data, containing columns like 'EVENT ID', 'TIMESTAMP, 'USER ID, and 'EVENT_TYPE. The 'EVENT TYPE column contains string values representing different event categories. You want to create a Snowpark DataFrame, but due to the table's size, you only want to sample a small portion of the data for initial exploration and testing. Which of the following code snippets MOST accurately and efficiently creates a sampled Snowpark DataFrame named 'sampled_df containing approximately 1% of the rows from the 'RAW EVENTS table?
- A.

- B.

- C.

- D.

- E.

Answer: E
Explanation:
Explanation:Option A provides the MOST accurate and efficient way to sample 1% of the data using , seed-42)'. The 'frae parameter directly specifies the fraction of rows to sample. 'seed' ensures consistent sampling across multiple runs. Option B is inefficient because it calculates the total count of rows before limiting, which scans the entire table. Option C, uses 'randomSplit' , but it splits the data into two new dataframes. Option D, utilizes Snowflake's SQL sampling feature via 'session.sqr , is a valid alternative, but less idiomatic when using Snowpark API directly. Option E, the parameter 'n' is deprecated and has been removed. 'sample' requires 'frae parameter.
NEW QUESTION # 188
......
SPS-C01 Dumps - Pass Your Certification Exam: https://www.getvalidtest.com/SPS-C01-exam.html
Latest Real Snowflake SPS-C01 Exam Dumps Questions: https://drive.google.com/open?id=14z80wSl4AwstEXhNc5ia-7lQR2zWXp8K